One expensive supervisor, a free local workforce: the core Harness pitch
Agent Harness pairs one capable cloud model as supervisor with a pool of free local models doing bounded, verified coding work.
By Agent Software
The wedge Agent Harness is built around
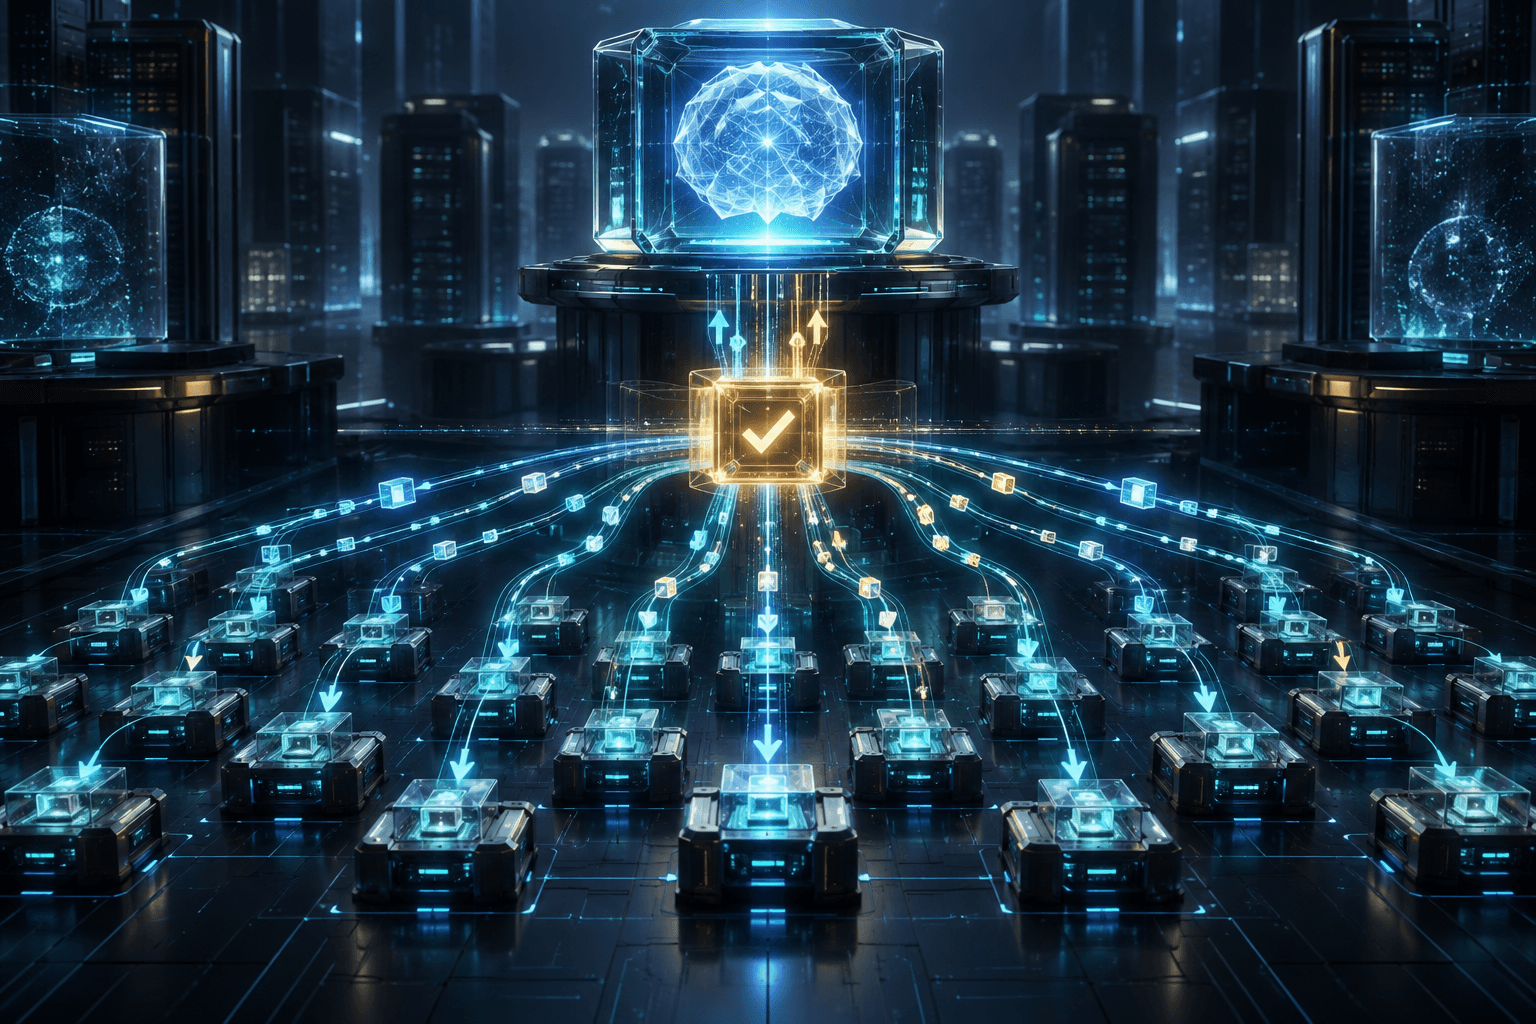
There's a wasteful pattern in a lot of agentic coding setups: routing every task, no matter how small, through the same expensive frontier model. Agent Harness starts from a different split — an "architect" model plans and reviews, while a pool of free local models, run through LM Studio or Ollama, does the bounded, mechanical coding work.
The expensive model's budget goes toward judgment: deciding what to do, and checking whether it was done correctly. The local models' job is narrower and doesn't need frontier-level reasoning to do well.
Why local models can be trusted here
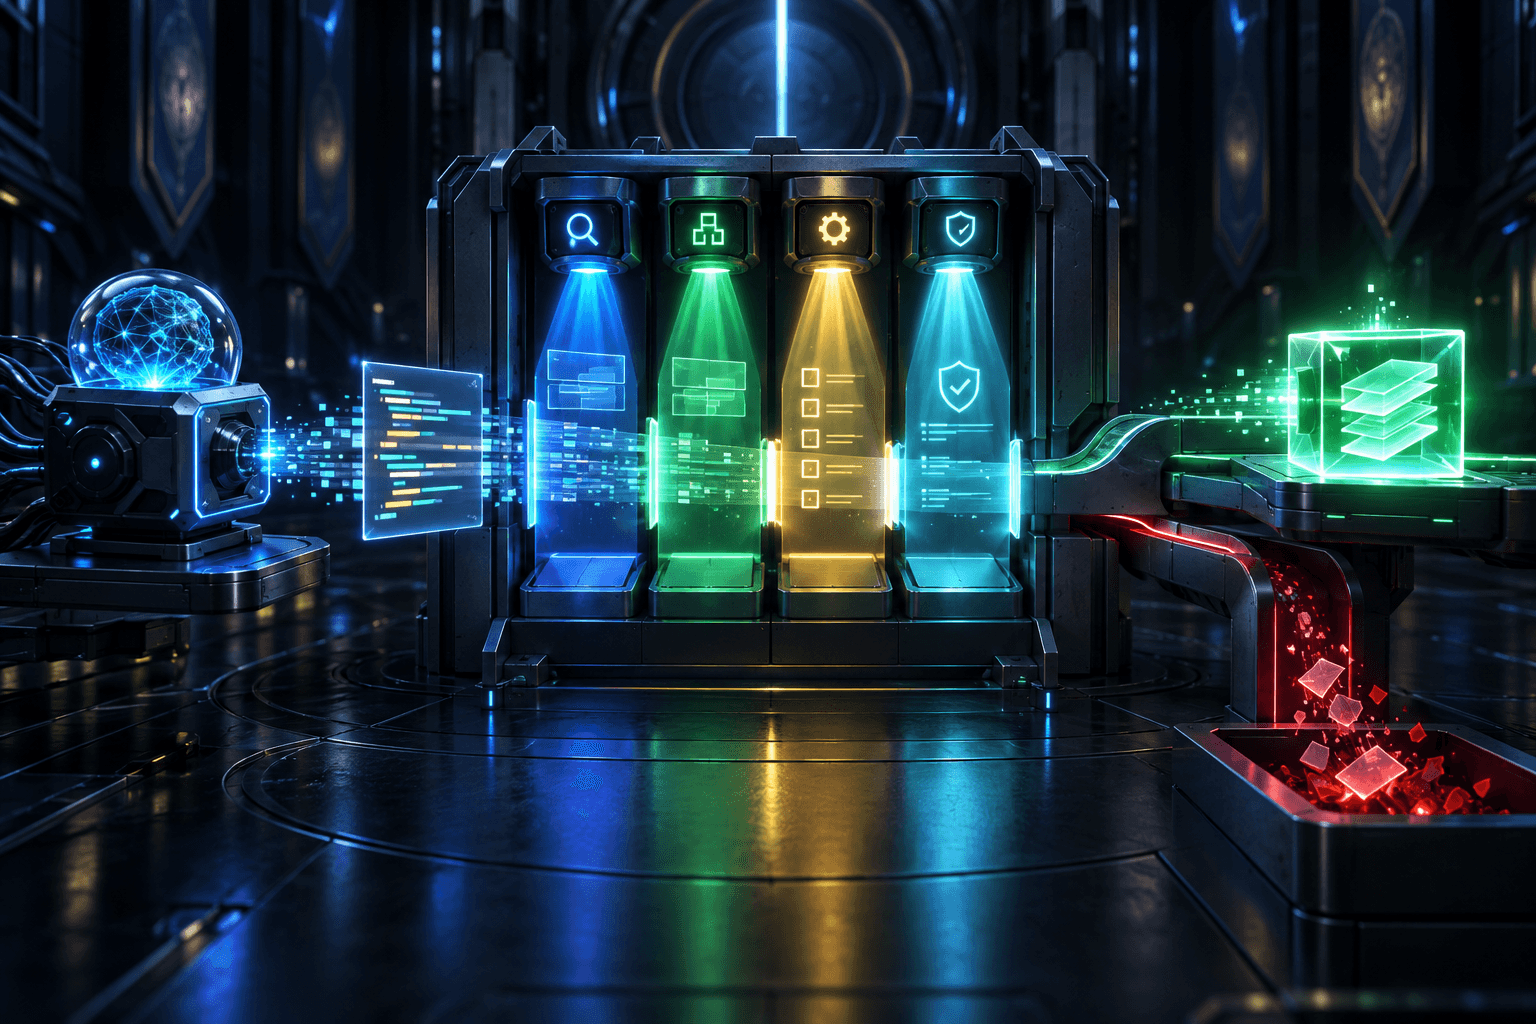
The honest answer is that they can't be trusted on their own — and Harness doesn't ask you to trust them on their own. Every edit a local model produces has to pass a deterministic verifier gate before it's accepted: scope checks (did it touch only what it was supposed to), expected-text checks, actual test runs, and policy checks. A local model's output that fails any of those gates gets rejected, not merged.
That's the core insight: the trust doesn't come from the model being good. It comes from the gate being strict.
What this actually saves
Because the bounded edits run on local hardware instead of a paid API, the marginal cost of iterating — trying an edit, checking it, retrying if it fails — drops close to zero. The expensive model gets called for planning and review, not for every attempt.
Where the cloud lane still fits in
Harness also supports a cloud-efficient lane for tasks that genuinely benefit from a stronger model's reasoning, with cache-aware token accounting to keep that lane efficient rather than defaulting everything expensive by habit. The point isn't "never use the cloud" — it's "use the expensive thing for what actually needs it."
Who this is built for
Harness is explicitly positioned for solo developers and small teams running local models who want a trustworthy way to delegate bounded coding work — not a fully autonomous agent that commits code unsupervised. The verifier gate and approval flow exist because that trust has to be earned on every run, not assumed once.