The pre-send guard: deciding reuse, rewrite, or send before a prompt costs you anything
How Agent Terminal's pre-send guard decides whether to reuse a prior answer, rewrite a prompt, or send it as-is before it ever reaches an LLM.
By Agent Software
Most cost control happens too late to matter
Dashboards, budgets, and spend alerts are useful, but they all operate after a prompt has already been sent and billed. None of them can undo a request that didn't need to happen in the first place. The only point where you can actually avoid a cost is before the request goes out — which is exactly where Agent Terminal's pre-send guard sits.
Three options, evaluated before anything is sent
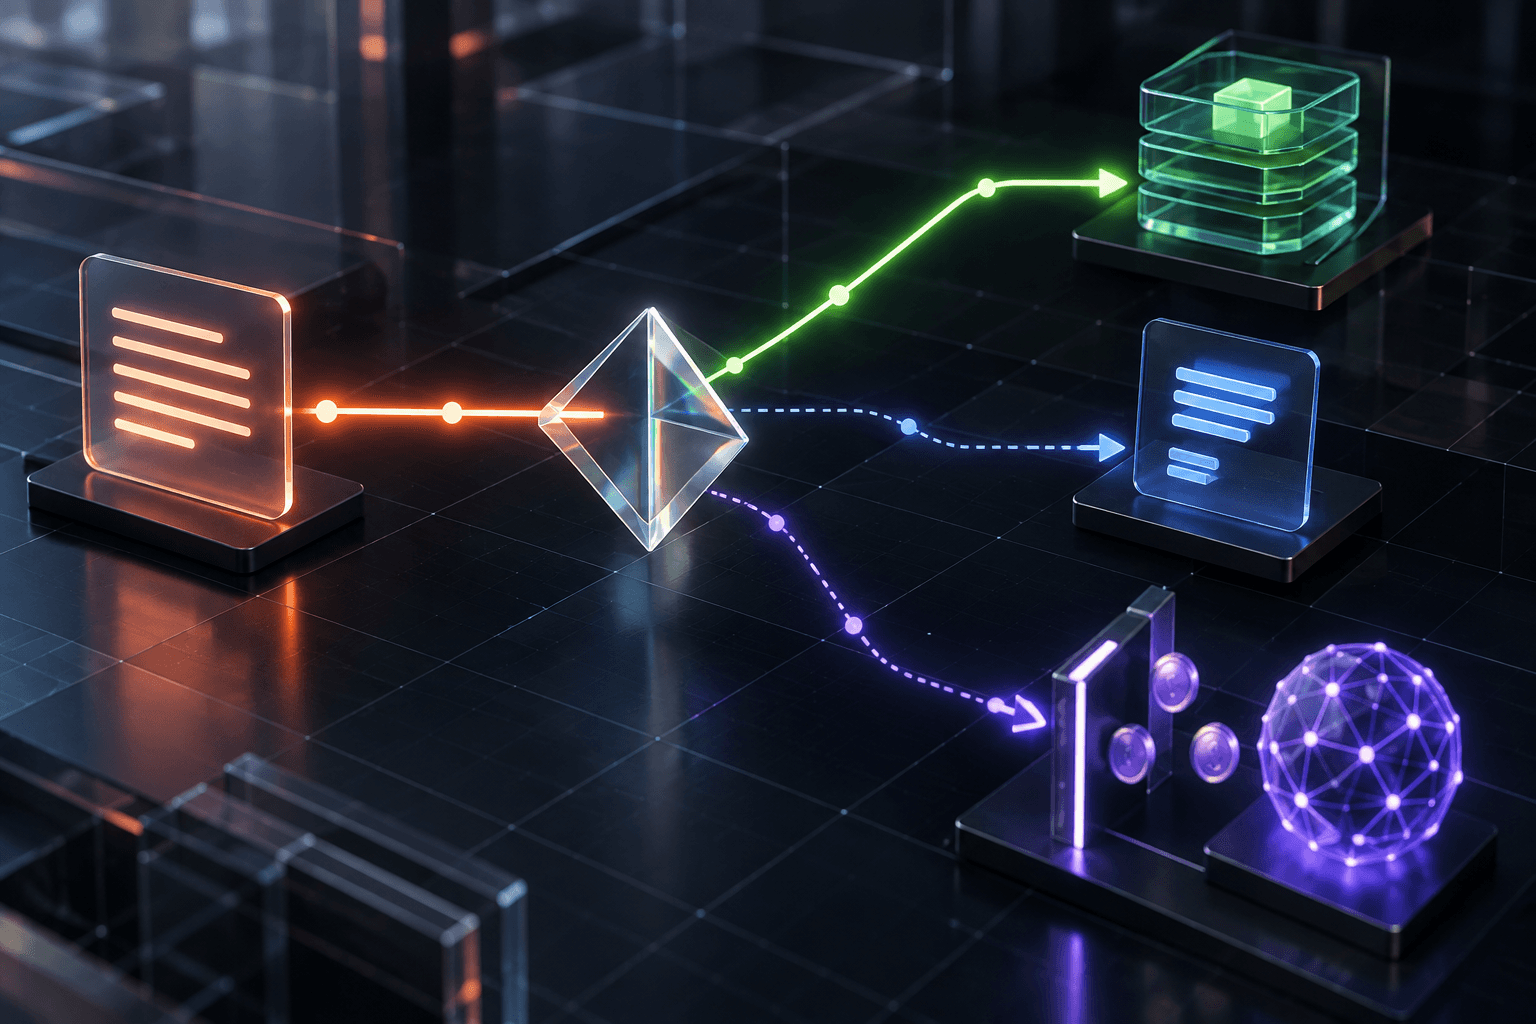
Every prompt passes through a pure decision engine — no side effects, just a ranking — that considers three paths:
- Reuse a prior answer that already covers what's being asked
- Rewrite the prompt into a cheaper version that would get an equivalent result
- Send the prompt as originally written, if neither of the above clears the bar
Only the third option actually reaches the model. The first two are ways of getting a useful answer without paying for a fresh call at all.
Two thresholds keep the guard honest
Reuse only kicks in above a minimum confidence bar — a default around 0.85 — so a prior answer only gets reused when it's genuinely likely to still apply, not just superficially similar. Rewrite only kicks in when it would save a meaningful number of tokens — a default around 100 — so the guard doesn't spend effort rewriting prompts where the savings wouldn't be worth it anyway. Both thresholds are tunable, which matters because the right balance depends on how repetitive a given workflow actually is.
Why this matters more in agent-assisted coding specifically
A coding session with an AI agent tends to repeat itself more than people expect — the same clarifying question, the same style of request, the same context restated slightly differently. That repetition is exactly what makes a reuse-first guard valuable: a meaningful fraction of prompts in a real session are close enough to something already answered that reuse is the correct choice, not a corner cut.
What "no side effects" buys you here
Because the guard's decision logic is pure — it doesn't mutate state or depend on anything beyond the prompt and the history it's checking against — it's straightforward to test, tune, and reason about independently of the rest of Terminal's execution pipeline. That separation is what makes it safe to adjust the thresholds without touching anything else.